The problem: visual brand drift
Ask an image model for the same product in 3 different advertising
contexts and you get 3 different products. The bottle changes silhouette.
The label typography drifts. The finish goes from matte to gloss. Each image is
individually good and the set is useless, because a campaign is only a campaign
if the thing being advertised is recognisably the same thing.
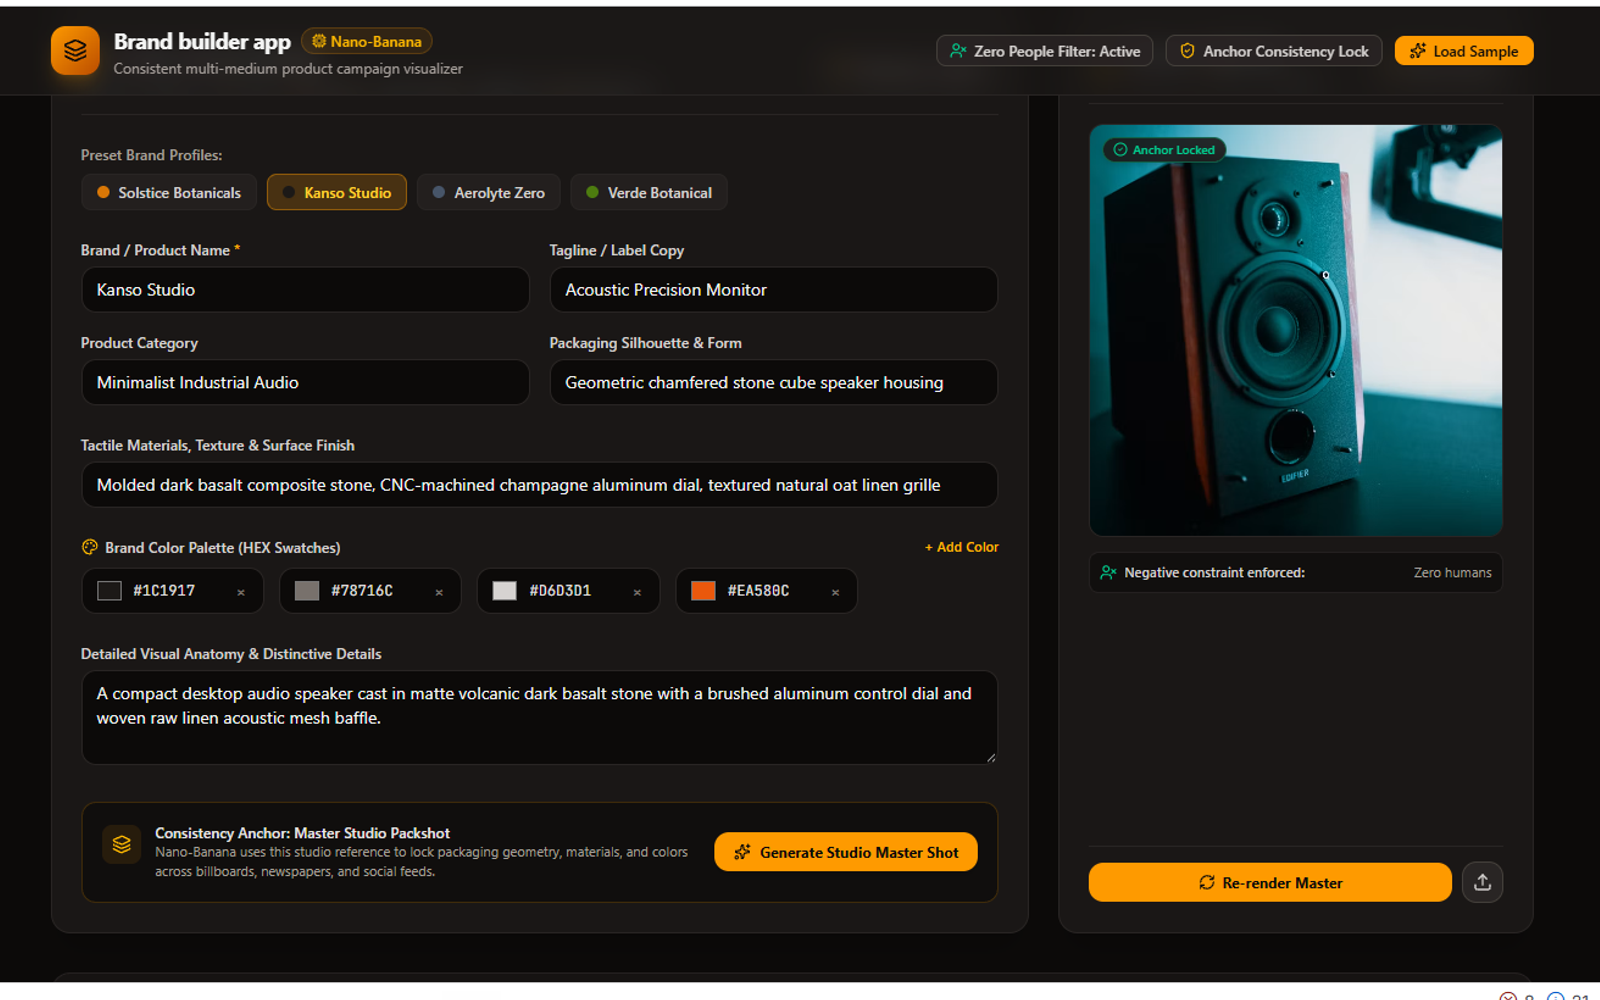
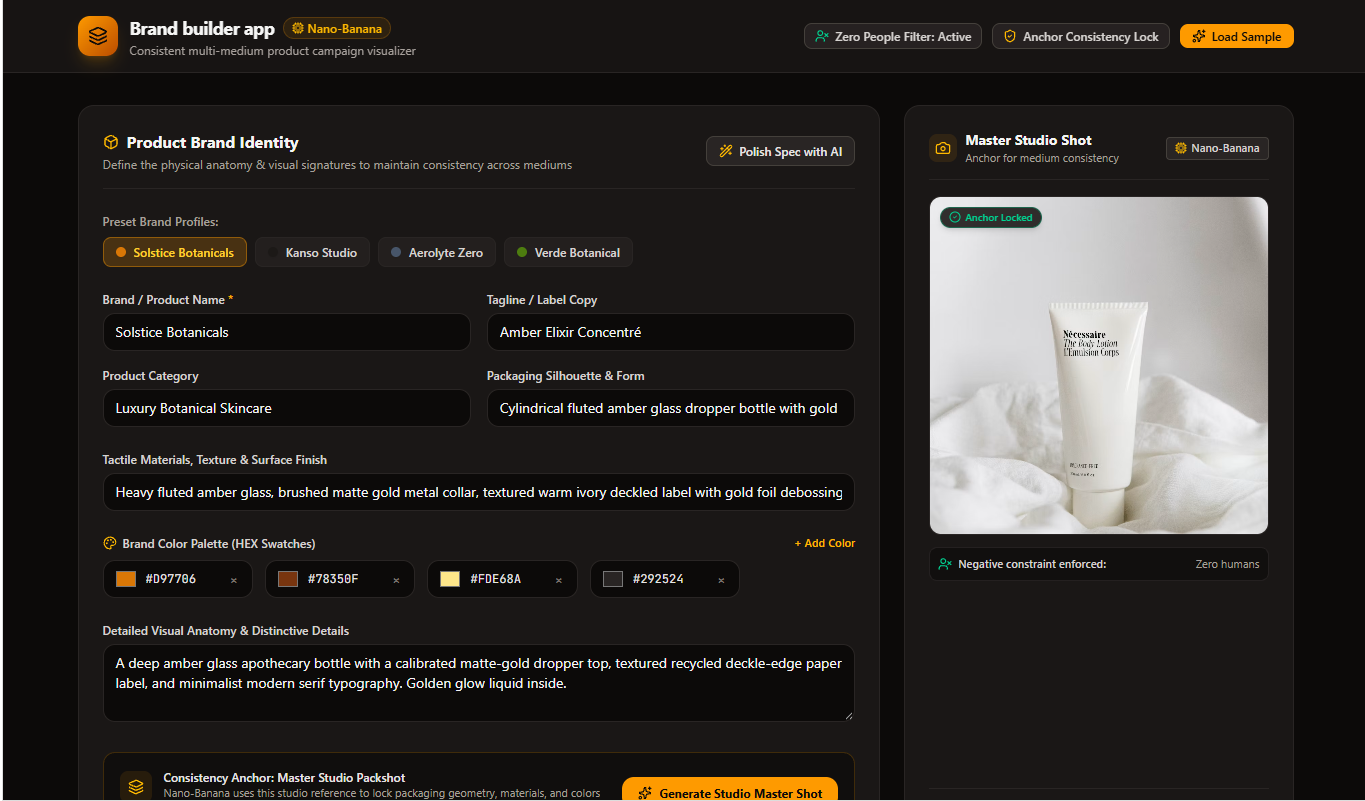
Brand Builder takes a product concept and produces a coherent multi-medium
campaign: highway billboard (16:9), broadsheet newspaper (3:4), social post
(1:1). The technical problem is entirely consistency.
2-phase conditioning, not better prompting
My first instinct was to describe the product more precisely in each prompt.
That does not work — text alone leaves the model too much freedom.
What works is anchoring every render to a single generated image:
- Brand DNA synthesis. Name, tagline, category, materials, packaging
silhouette and explicit hex colours become a fixed set of physical tokens —
“fluted cylindrical glass dropper”, “sandblasted titanium”, “amber glass
with gold foil debossing”.
- Master studio packshot. One unadorned shot of the product on a neutral
plinth. This is the anchor.
- Medium-specific synthesis. The master image’s raw base64 buffer goes into
the model’s multimodal input alongside the physical tokens, with the
instruction to place this exact product into the target medium.
The text tokens hold the description steady; the image conditioning holds the
geometry steady. Neither alone is enough.
The guardrail that took the most iterations
The brief required no people in any shot. Advertising prompts hallucinate
people relentlessly — commuters on the highway, hands holding the bottle,
models in the metro station. It took 3 layers:
- An explicit negative constraint in the system prompt, stated in absolute
terms and naming the specific failure modes: hands, faces, silhouettes,
pedestrians.
- Scene sanitisation. Billboards are prompted at twilight on empty
highways. Newspapers as flat-lays on a wooden table. Transit as an empty
architectural terminal. Choosing scenes with no natural reason to contain
people does more work than forbidding people.
- A prompt inspector in the UI, so the constraint can be verified as
transmitted on every generation rather than assumed.
That last one matters more than it sounds. A guardrail you cannot audit is a
guardrail you are hoping for.
Failing without crashing
Image generation on the free tier has a quota of zero, so the interesting path
is the failure path. The server intercepts RESOURCE_EXHAUSTED and 429s and
falls back to a deterministic SVG mockup rendered with the user’s exact
brand palette, packaging geometry and typography for the chosen medium. The
client receives a structured isQuotaNotice response and shows a banner
explaining that live rendering needs a billing key.
The user still sees their campaign laid out, still interacts with it, and
understands exactly why it is a mockup. Nothing hangs and nothing crashes.
Stack
React + Vite client, Node/Express proxy, TypeScript throughout. Gemini image
generation through the official @google/genai SDK. The API key never leaves
the server; the client only ever calls /api/imagine and
/api/suggest-product.
What I learned
Consistency is an architecture problem, not a prompting problem. Every
attempt to solve drift by writing a better description failed. Passing a
reference image solved it.
Negative constraints work better as positive scene choices. “No people” is a
rule the model can miss. “Empty highway at twilight” is a scene where a person
would be strange. The second survives more generations than the first.
Design the quota-exhausted path first. On a free tier it is the common case,
and the SVG fallback became the part of the app I was most pleased with — the
product stays useful at its least capable.